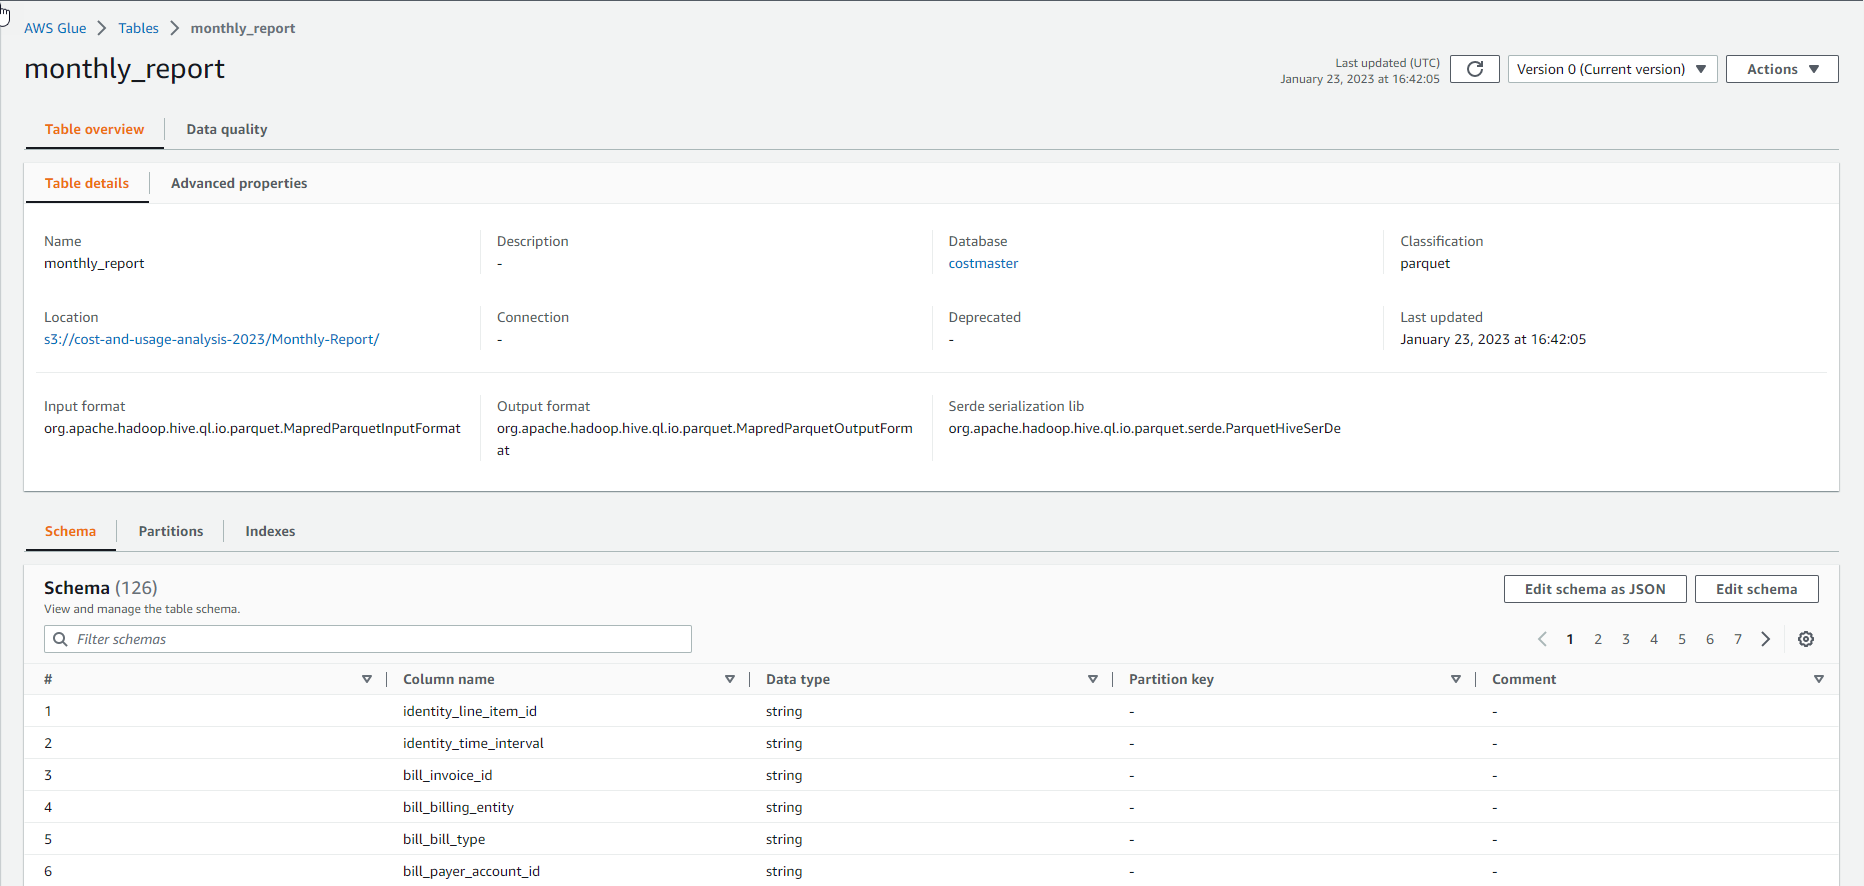
Build database
In the lab, once we have the input data with the path above as at the beginning of the lab, we will configure AWS Glue and Crawler to run on a schedule once a day. Crawler will scan the path containing the input Parquet file, save it on S3, and then create a database along with accompanying tables. When there is a new version of the report, the data table will be automatically updated.
Amazon Athena helps us access and view the contents of the parquet file via SQL commands. Amazon Athena is a serverless solution that supports executing SQL query commands on large amounts of data. Athena is only charged for the data scanned, unlike traditional database solutions.
The detailed configuration steps so that Amazon Athena can access data files via AWS Glue are as follows:
Access AWS Management Console
- Search AWS Glue
- Select AWS Glue
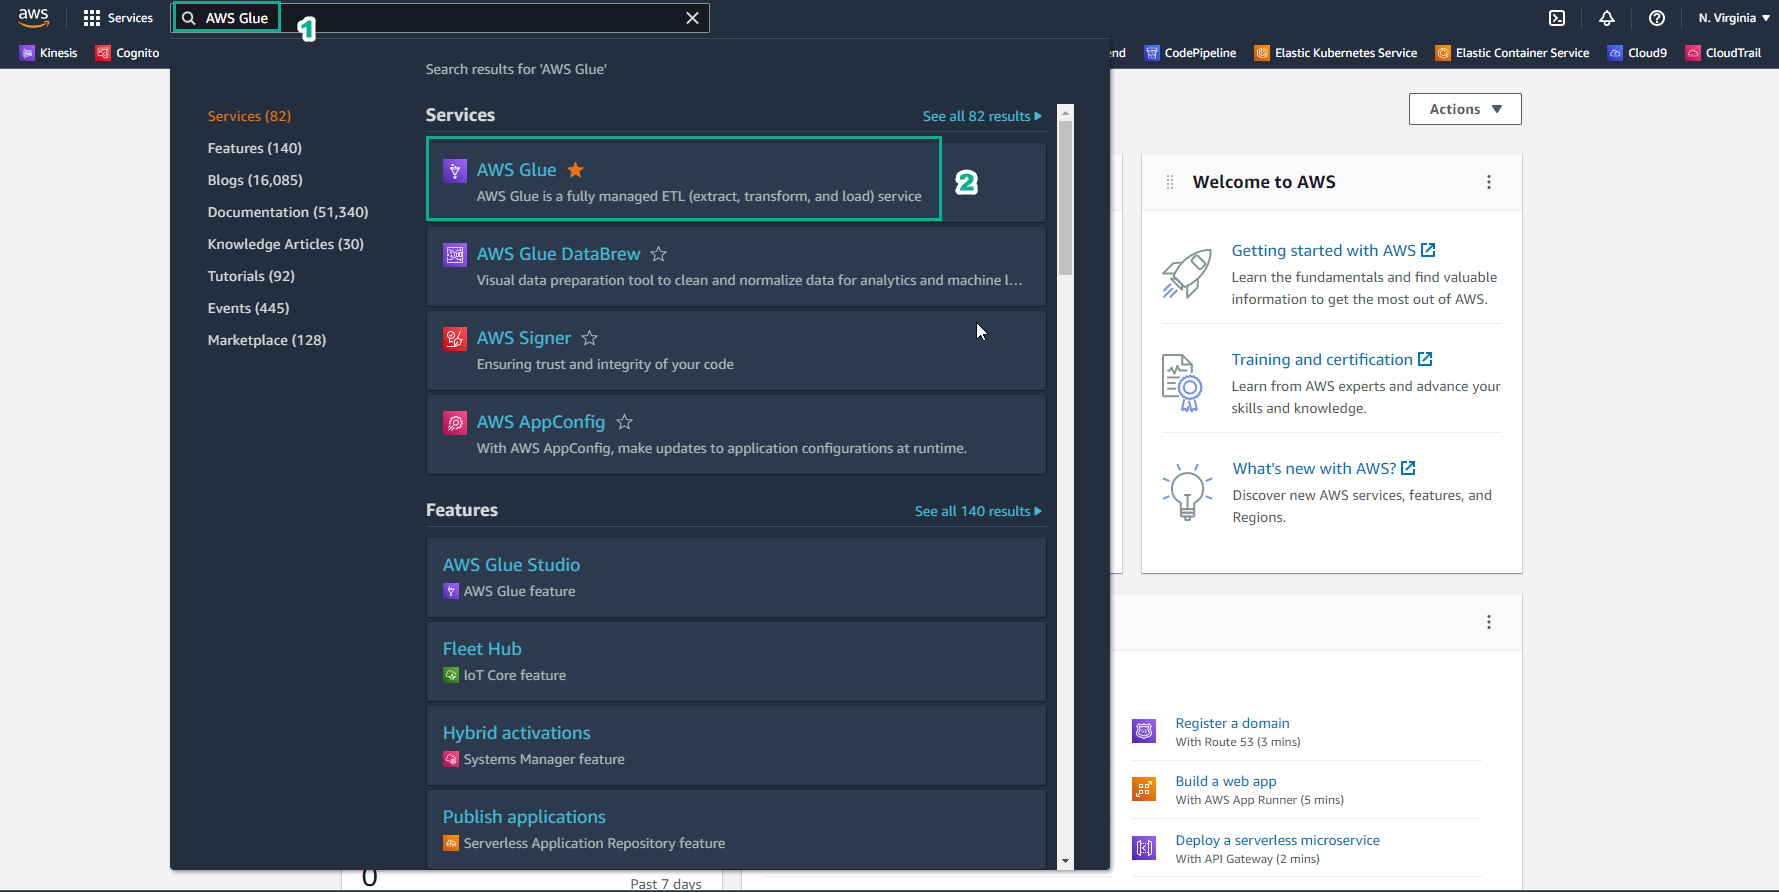
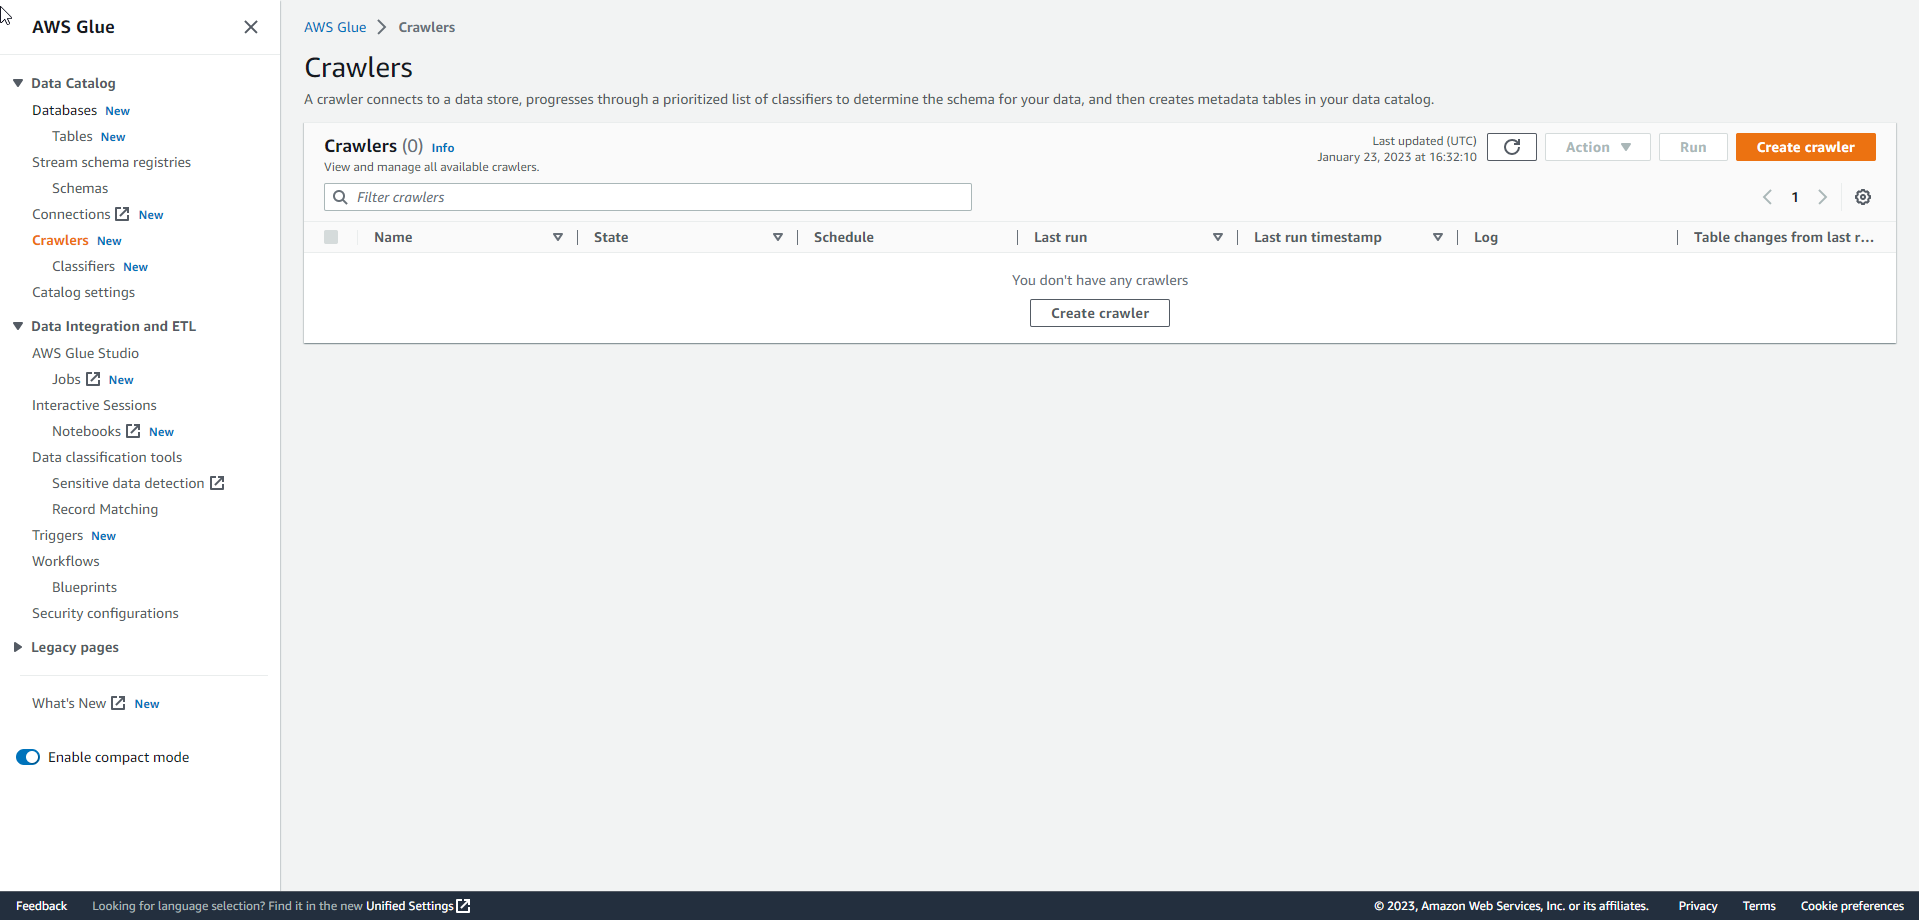
In the AWS Glue interface
- Select Crawlers
- Select Create crawler
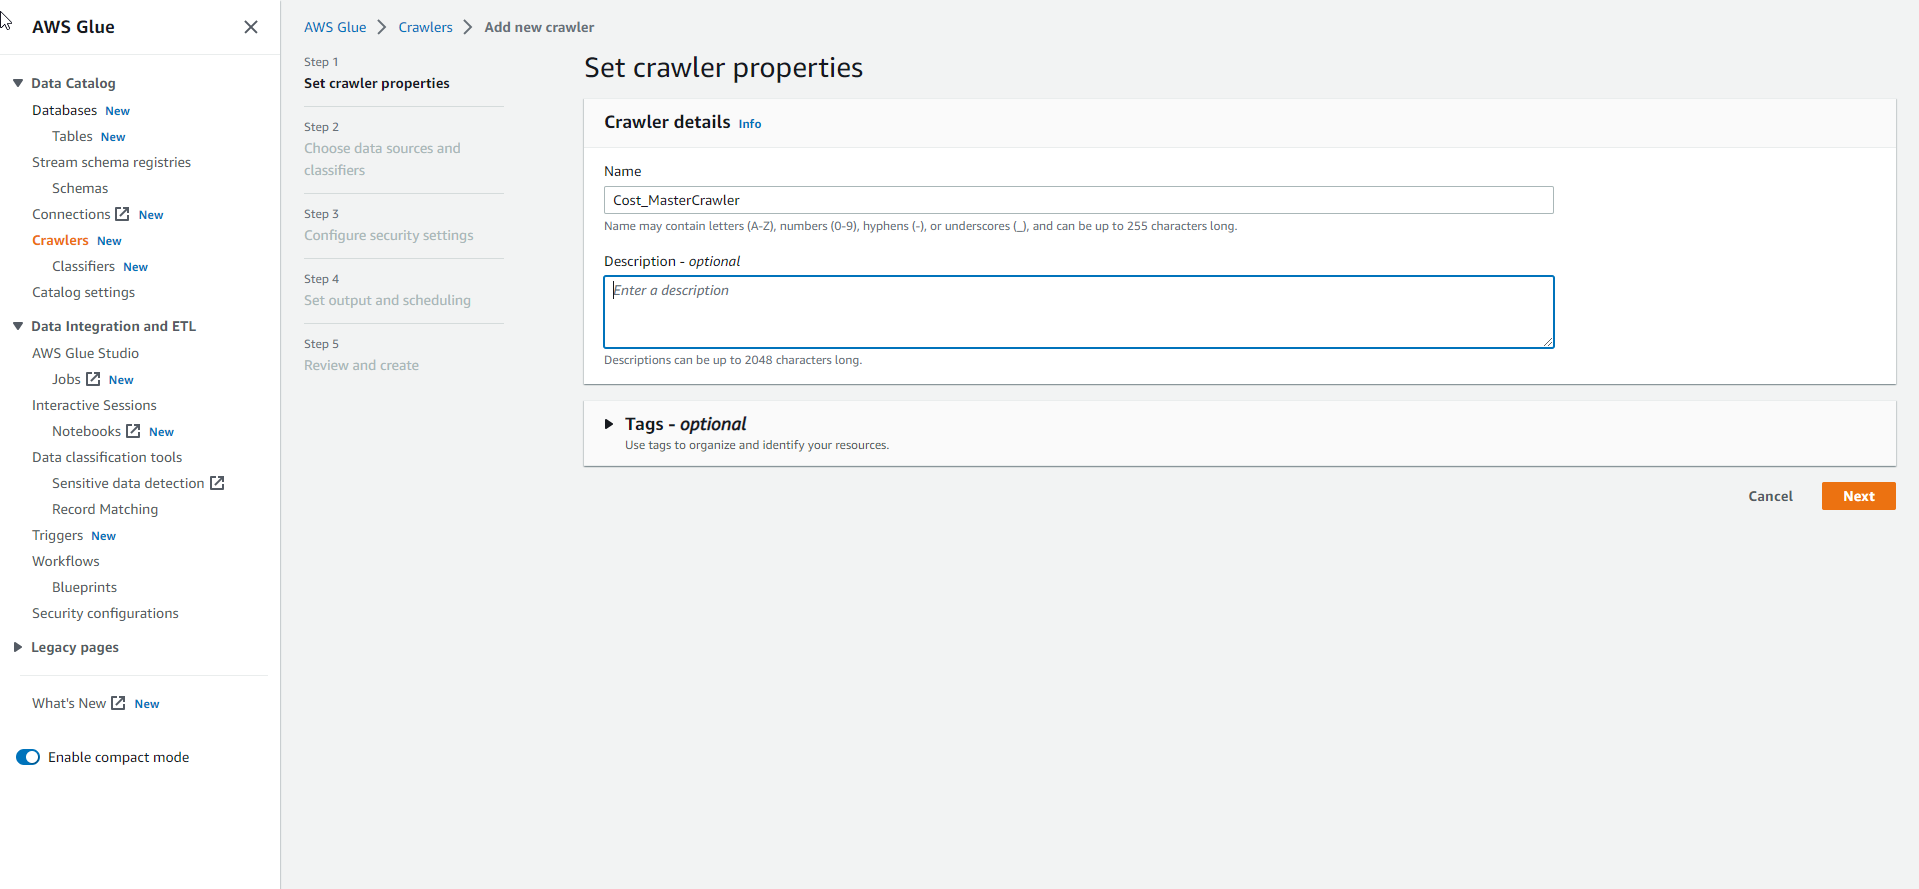
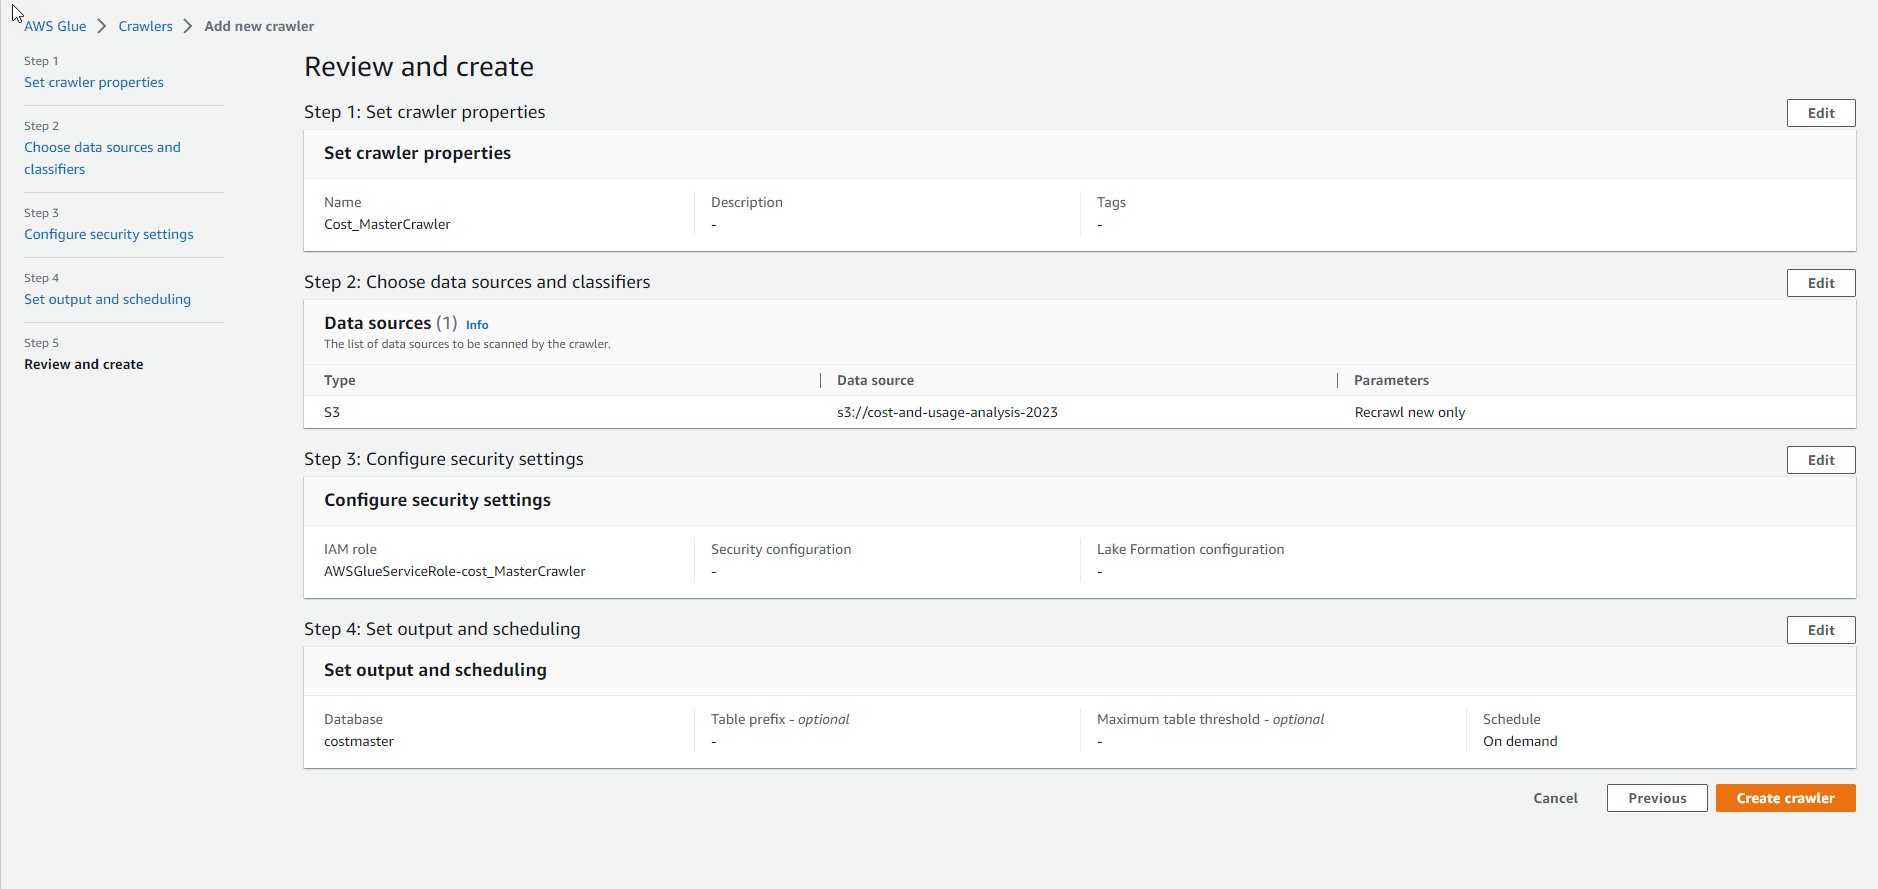
- Configure Crawler, enter Name as
Cost_MasterCrawler. Then, select Next
- Select Add a data source
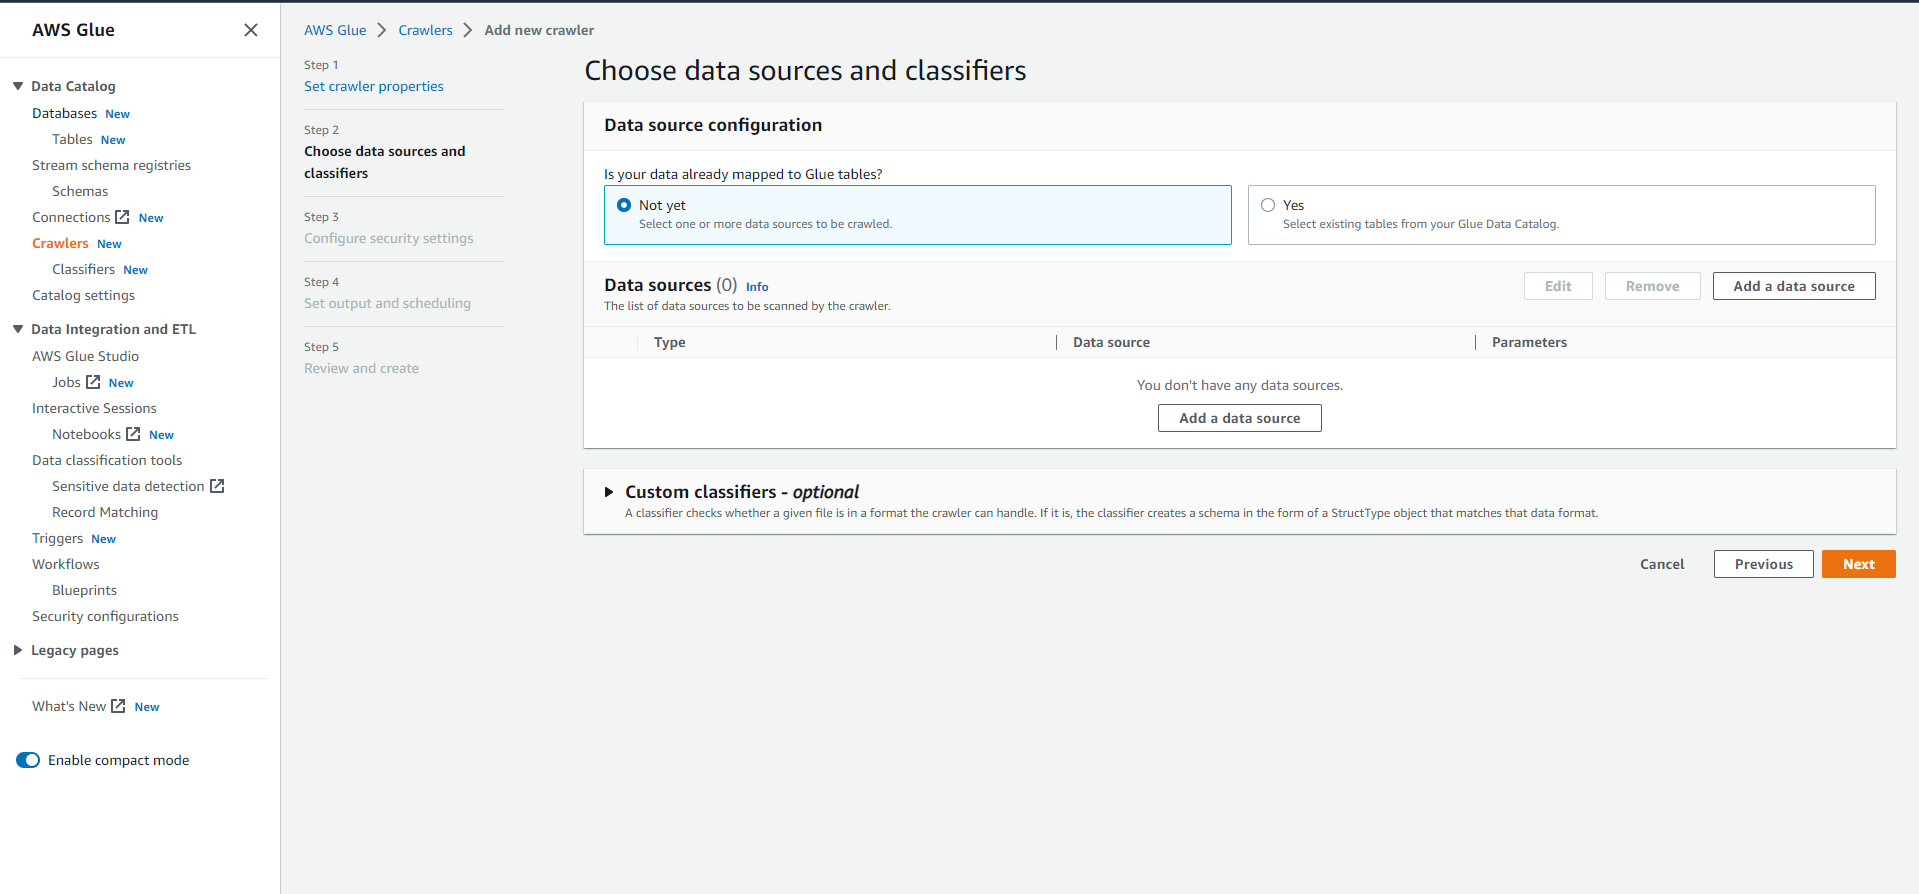
- Configure data source
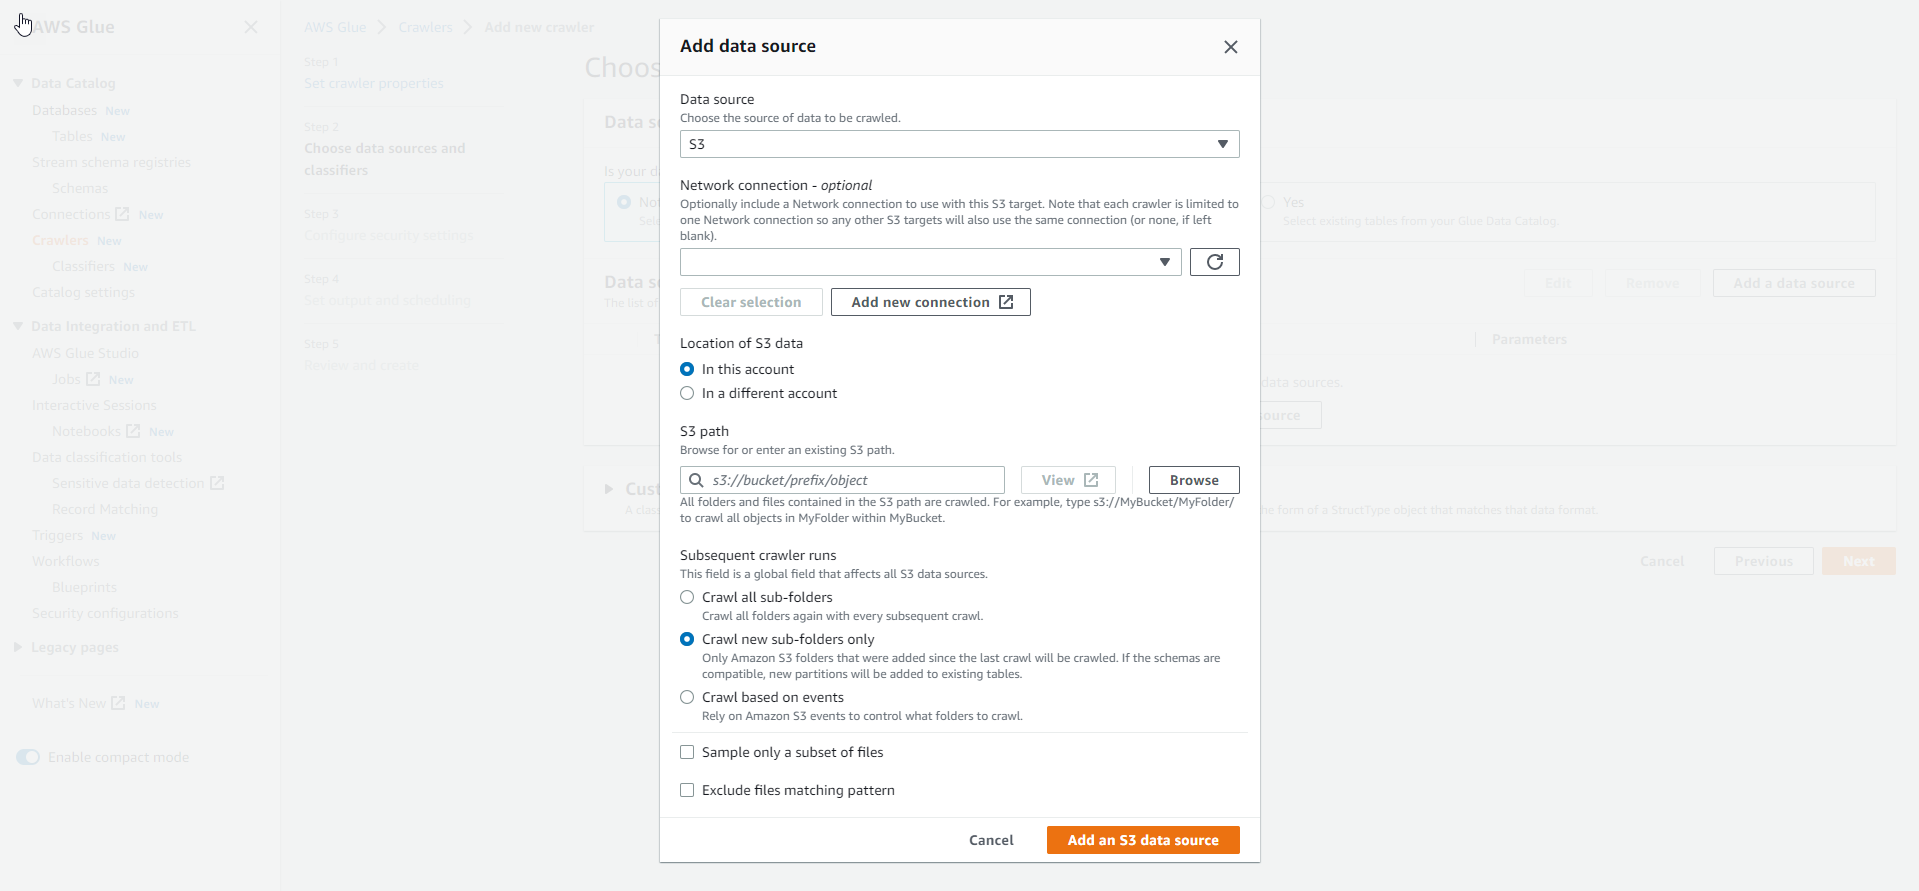
- Select S3 path
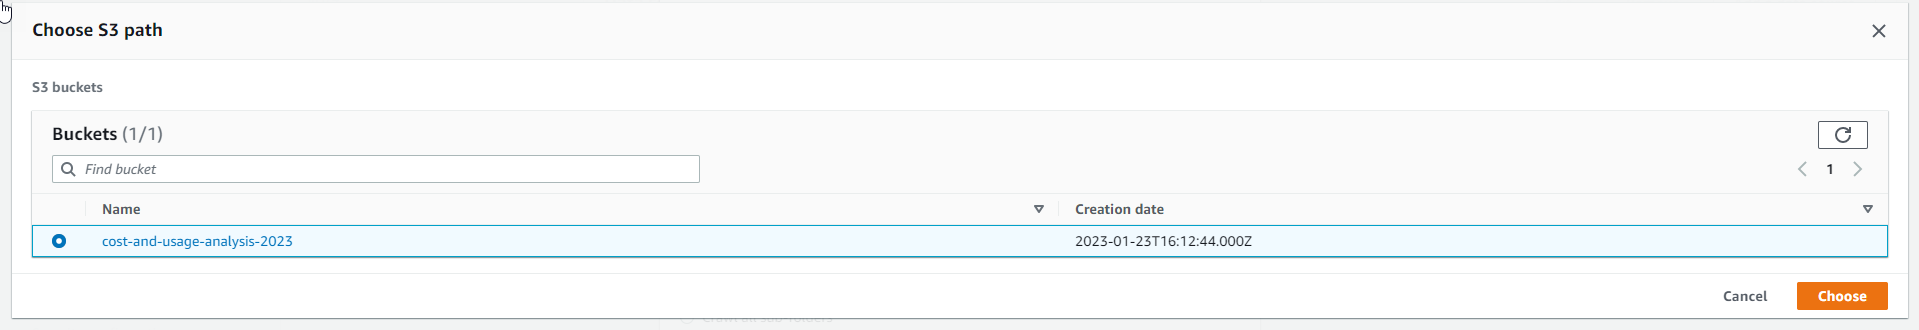
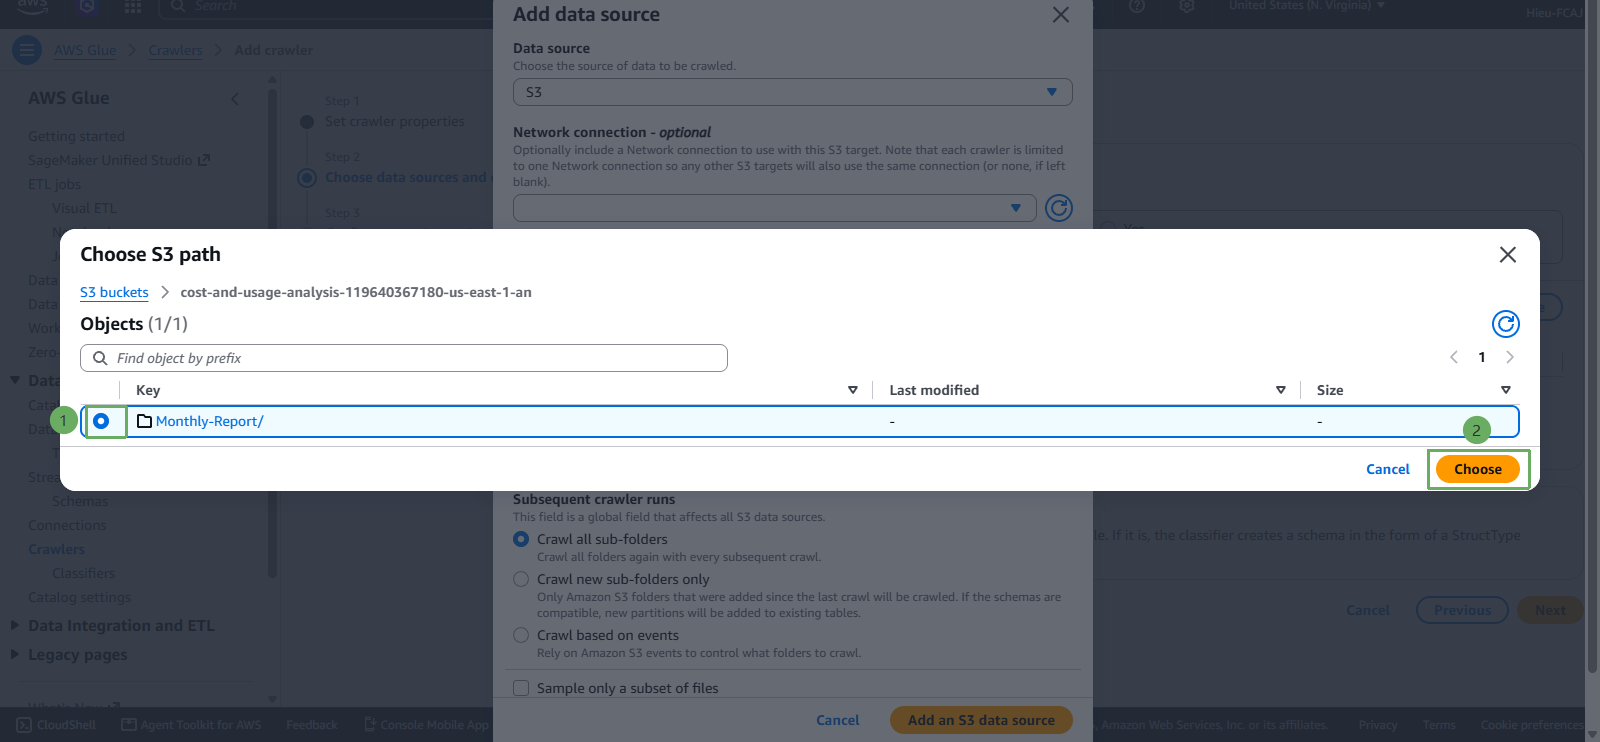
- Complete the data source configuration.
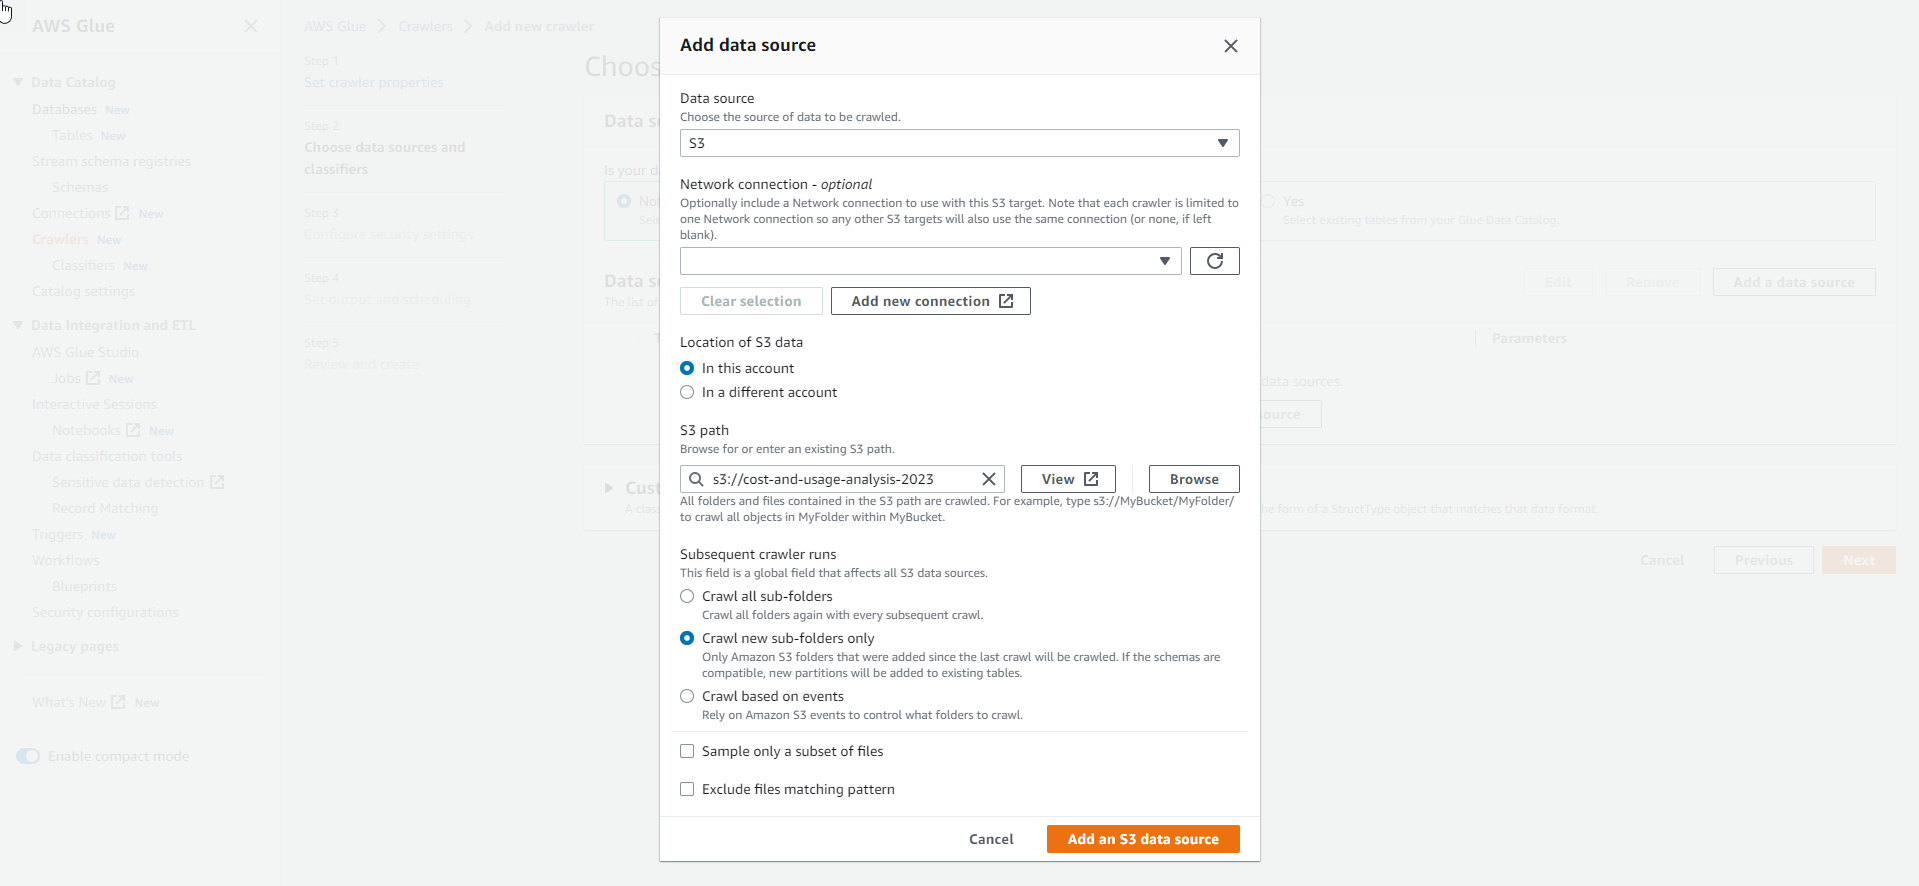
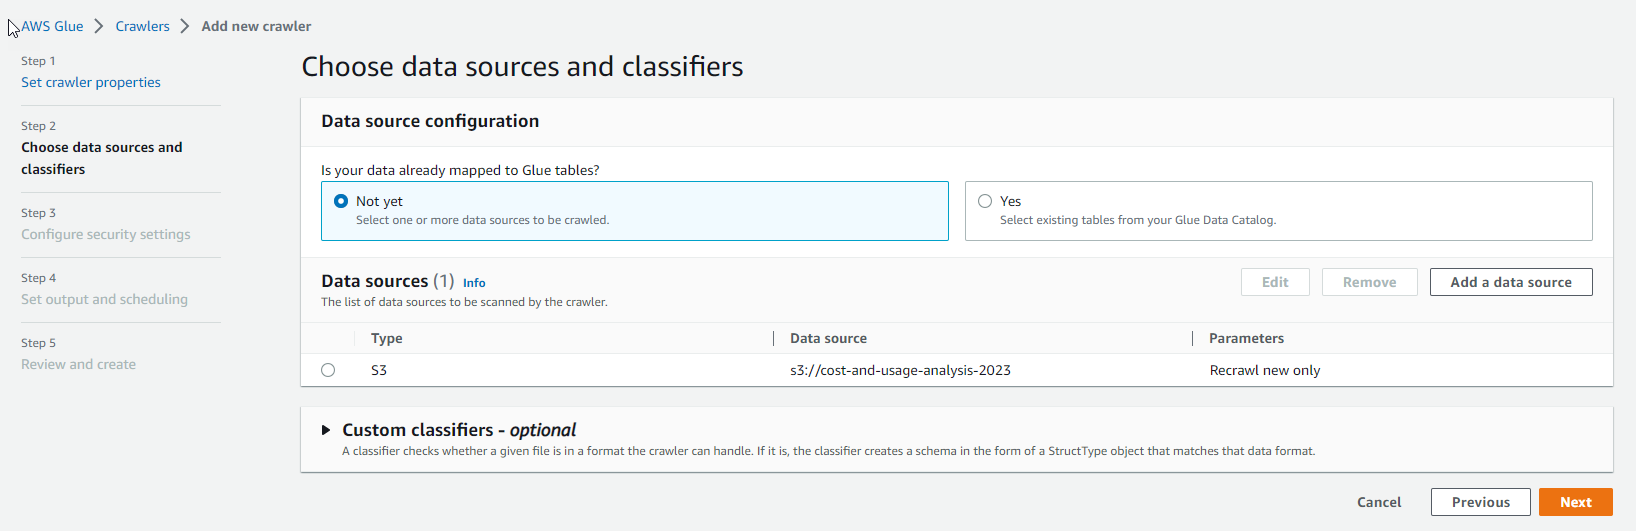
- After configuring the data source, select Next
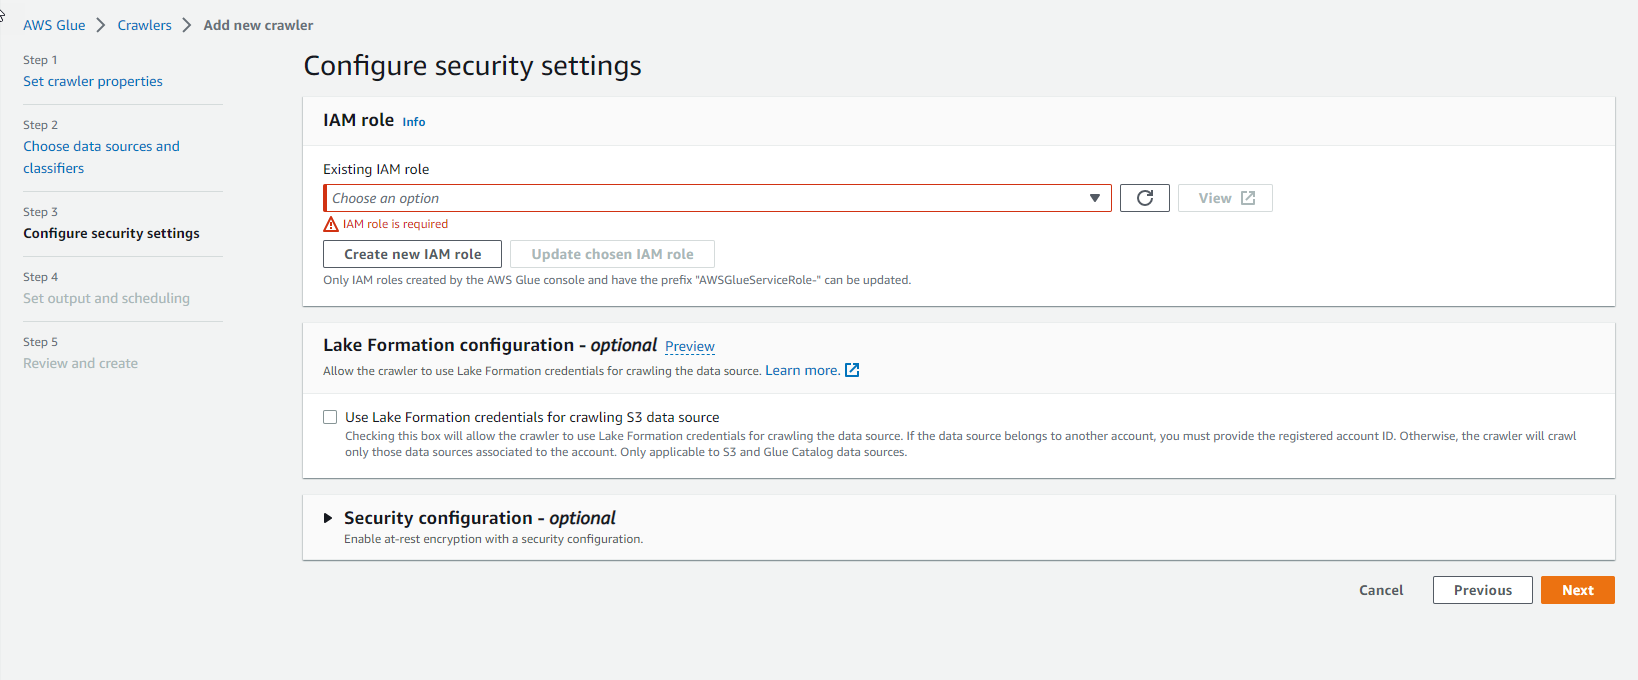
- For Configure security settings, you enter the role name AWSGlueServiceRole-MasterCrawler and click Next
- Proceed to add a database
- Select Add database
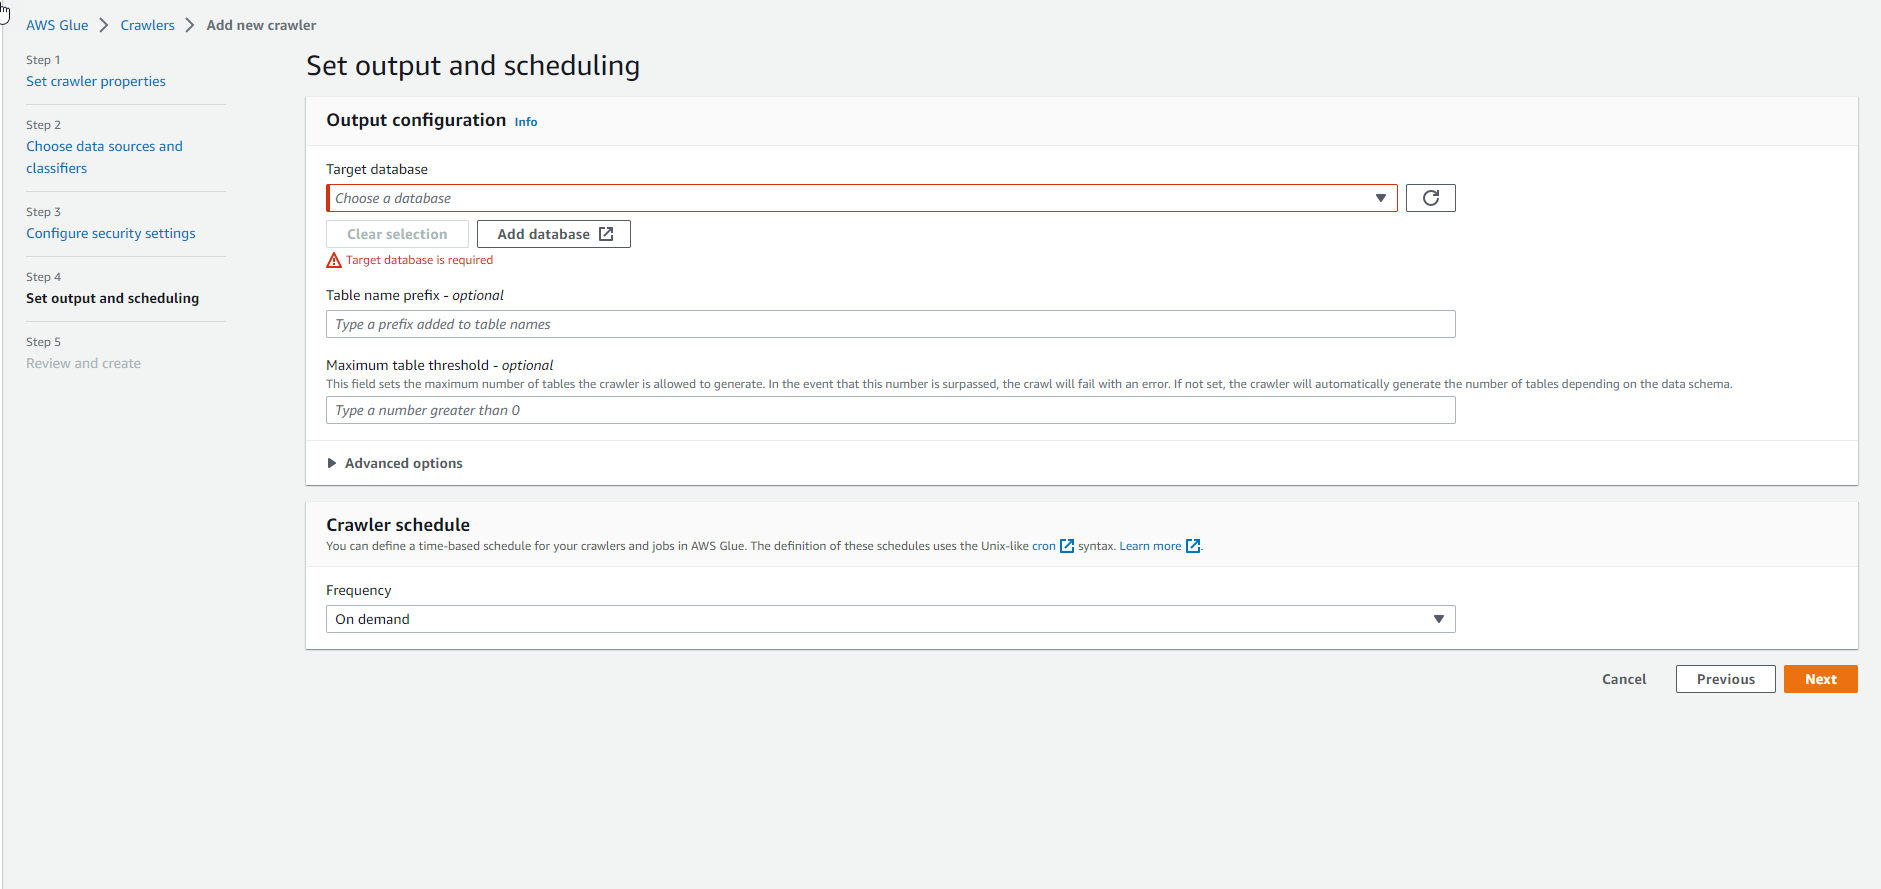
- Enter the database name as
costmaster. Select Create database
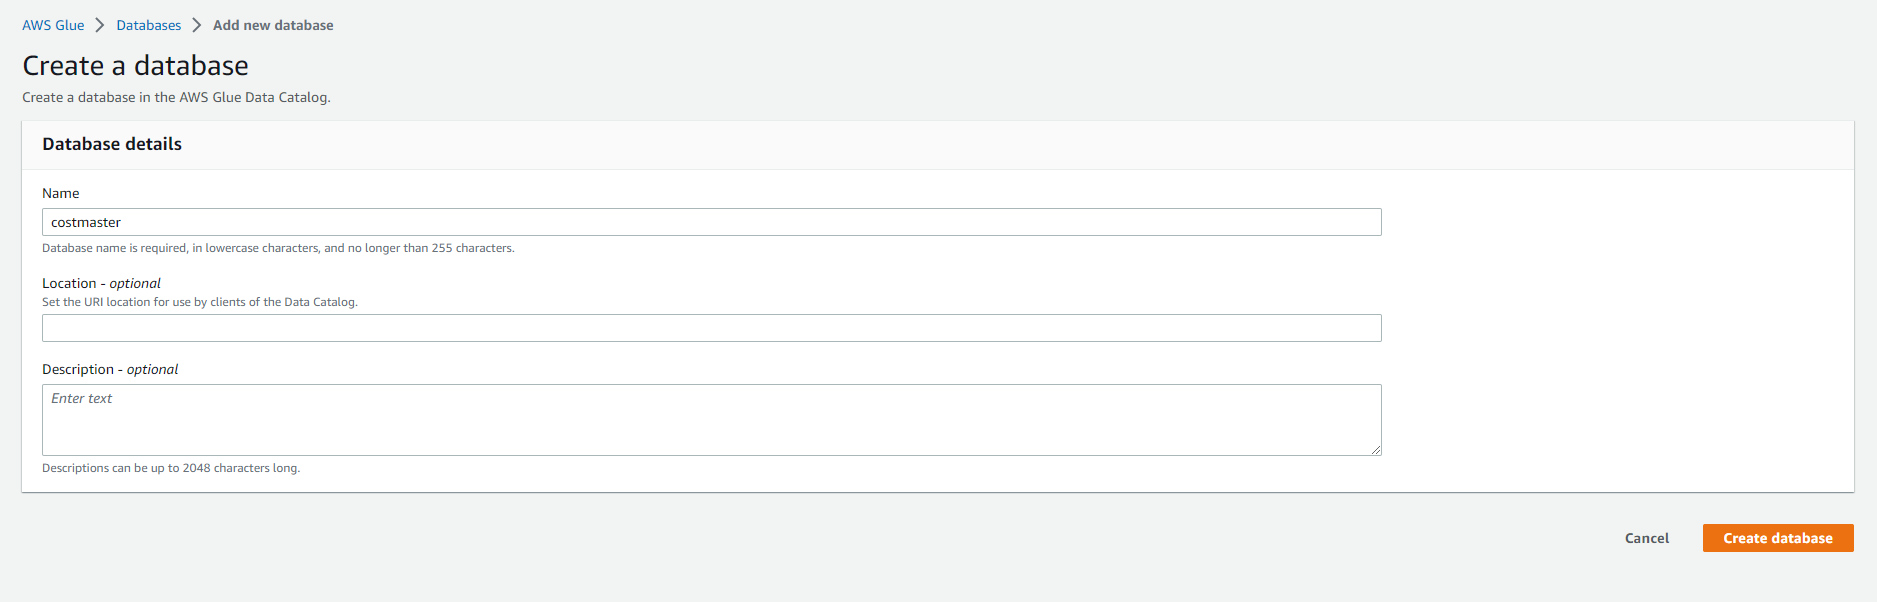
- Complete creating the database.
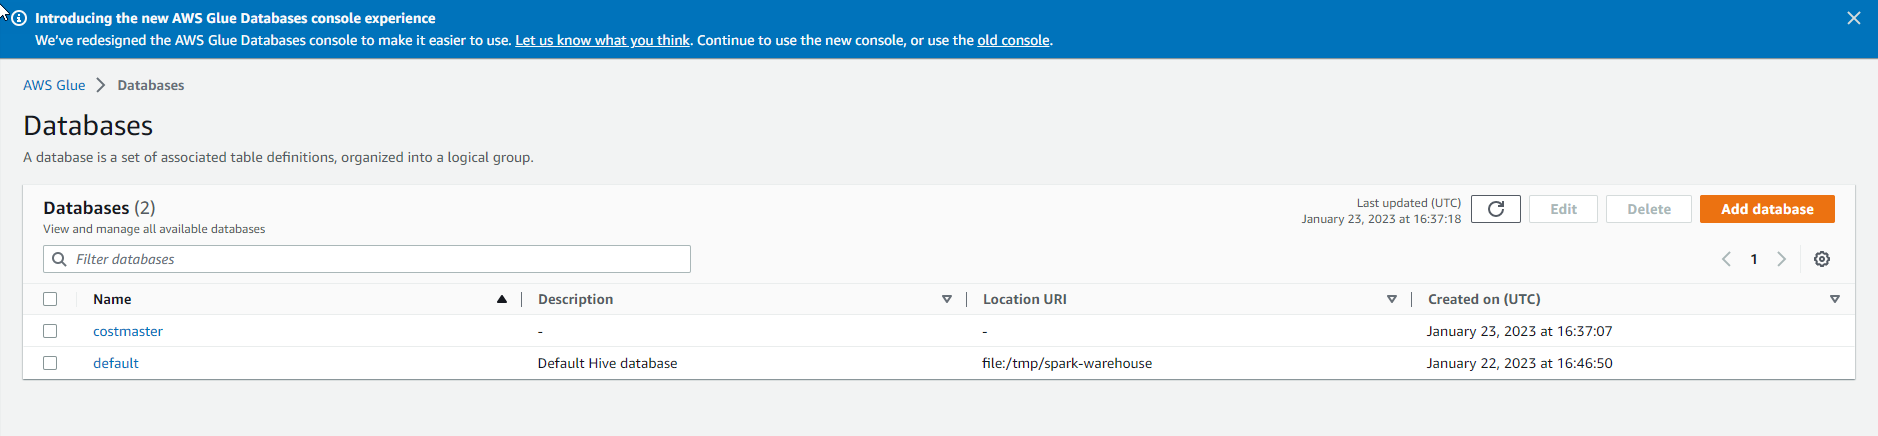
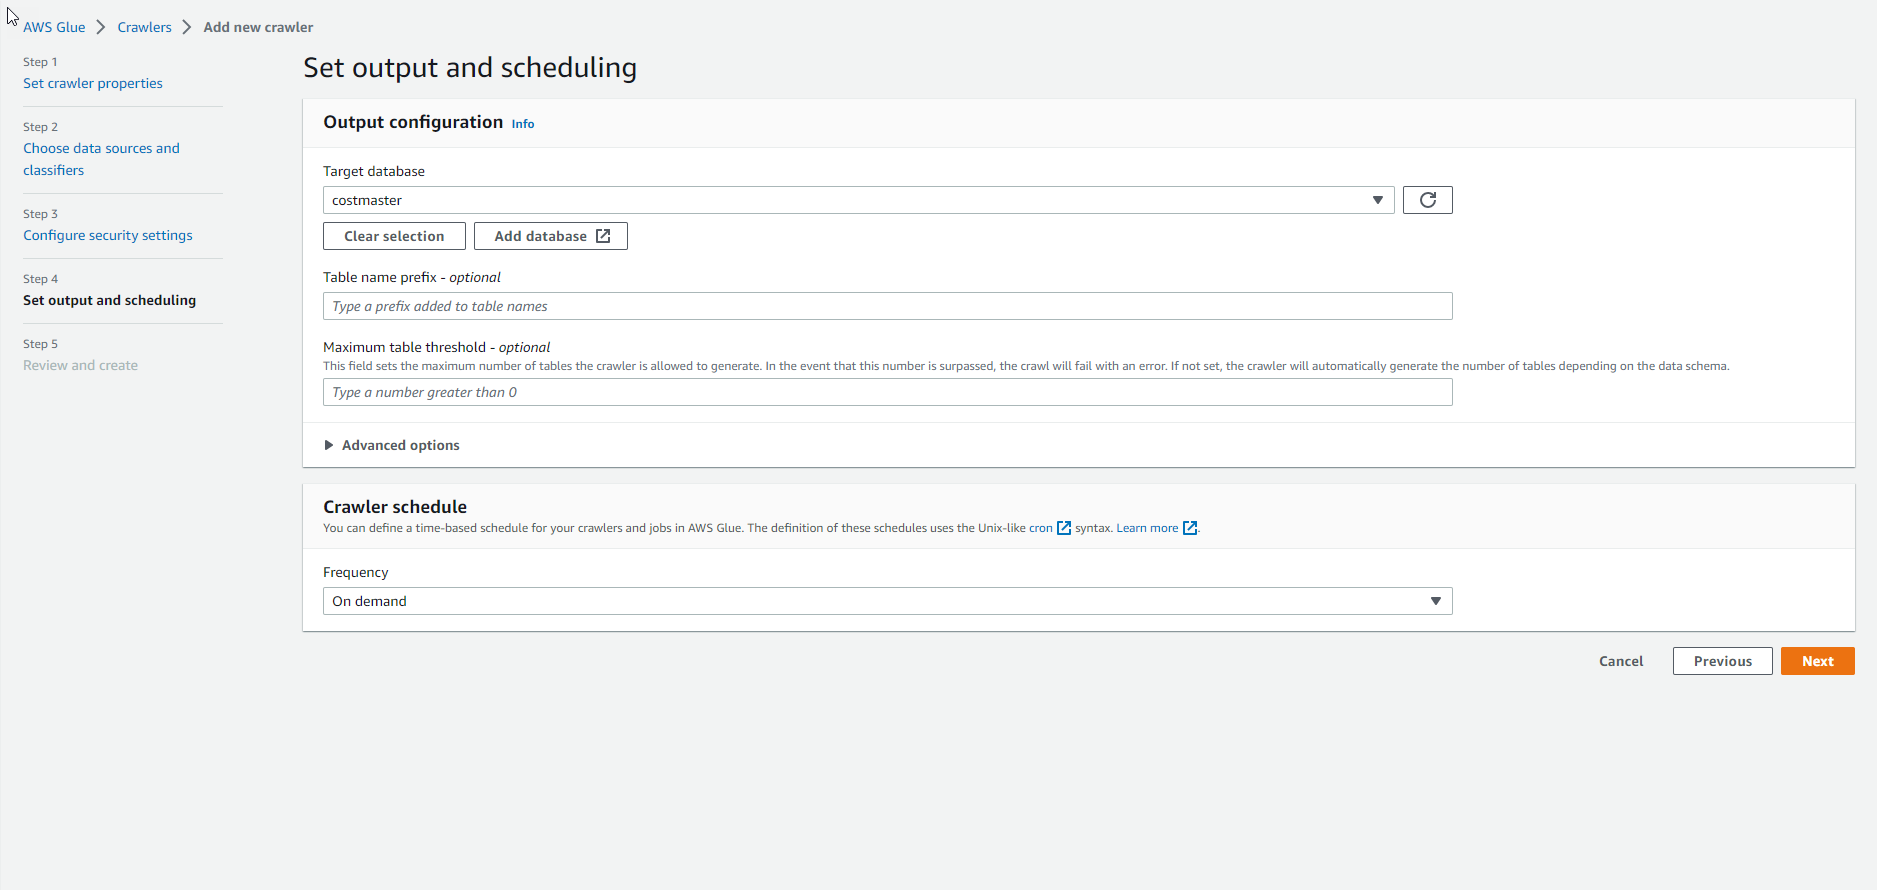
- Add the database successfully and select Next
- Review and select Create crawler
- Complete creating the crawler.
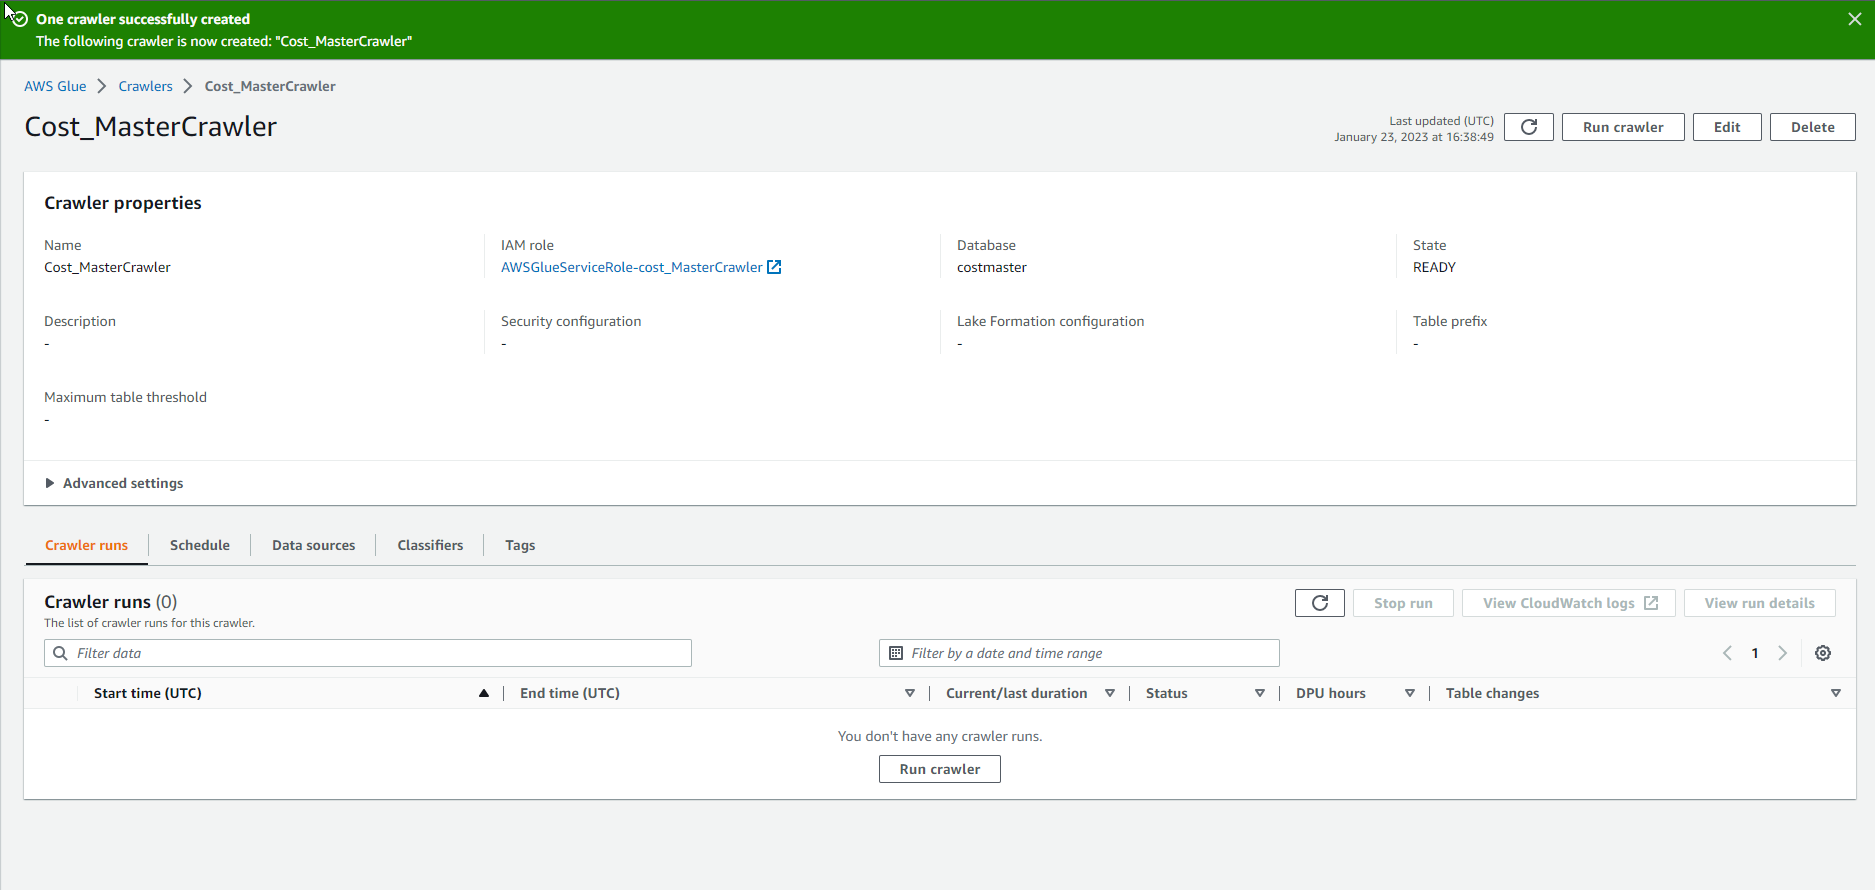
- Select Run crawler
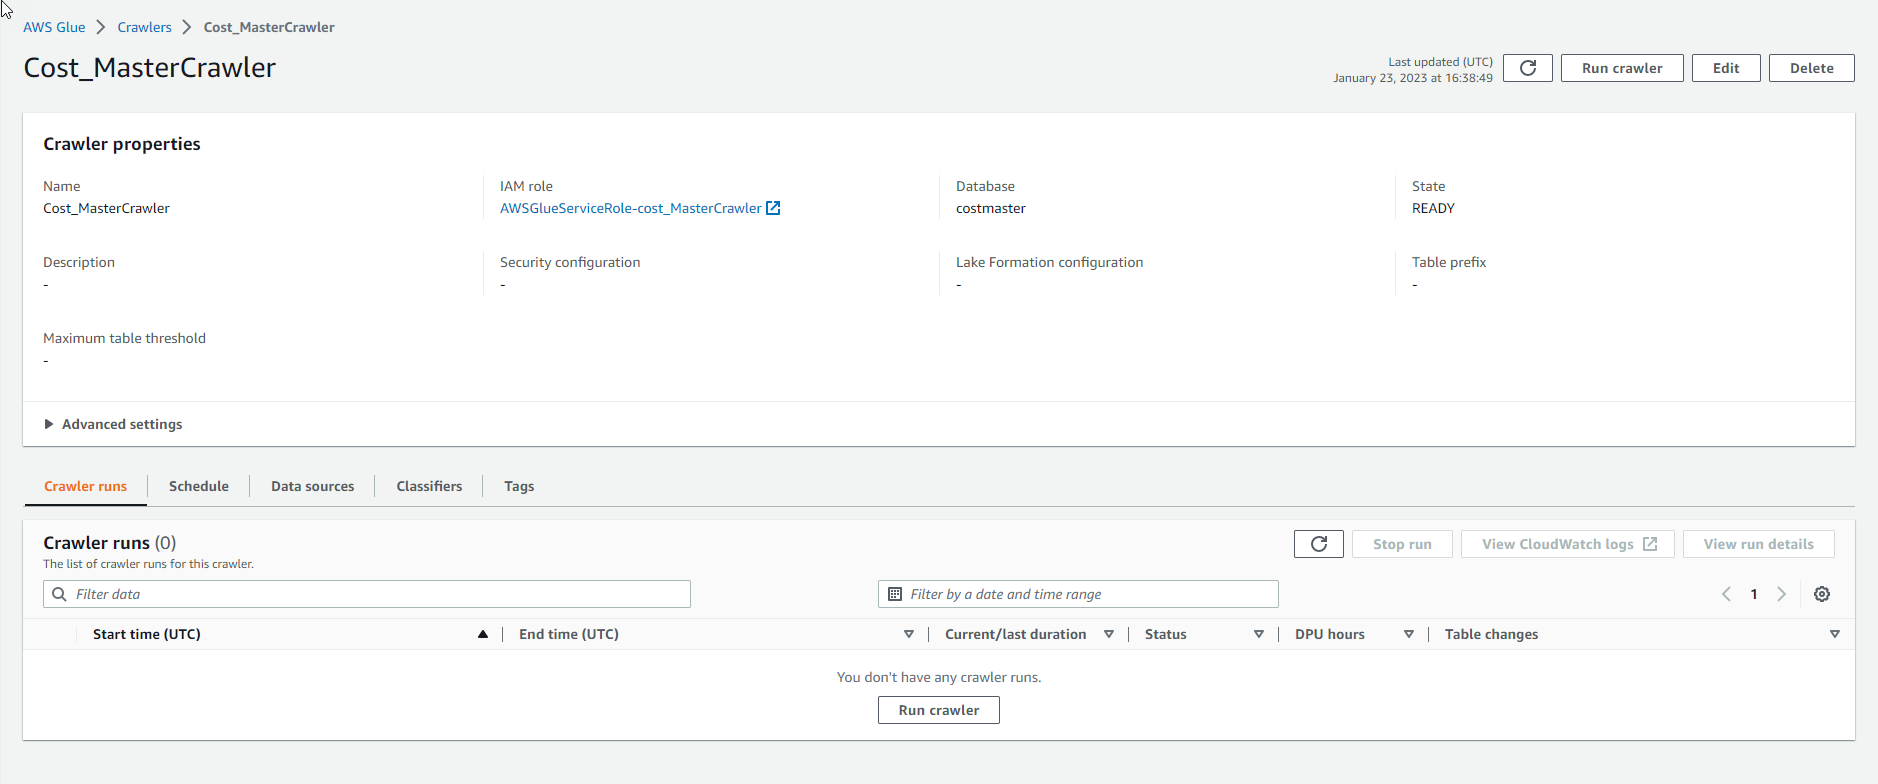
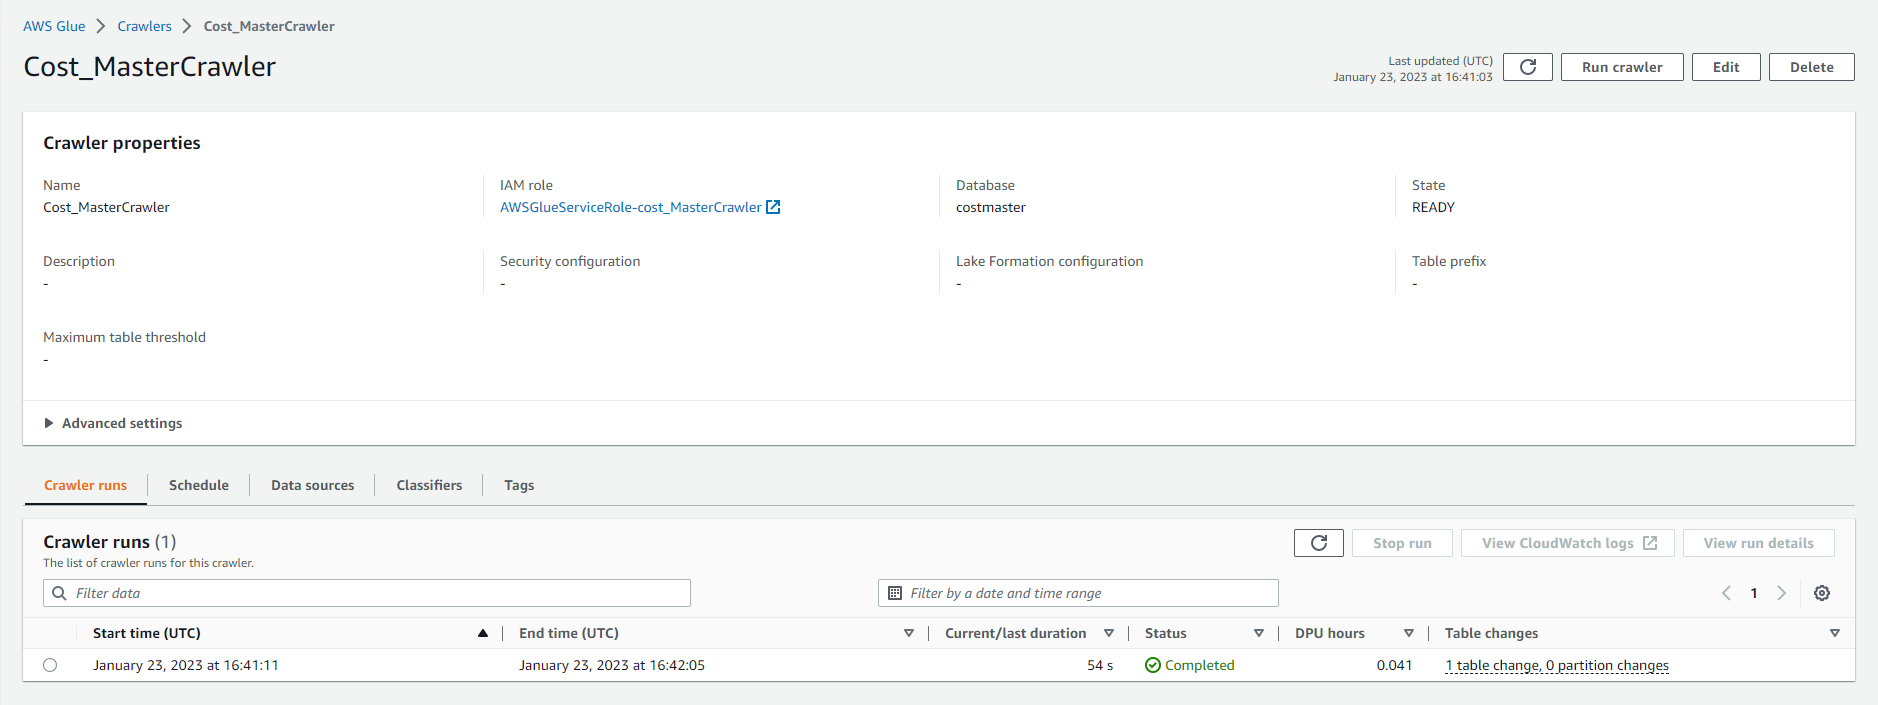
- It takes about 1 minute to initialize the run crawler.
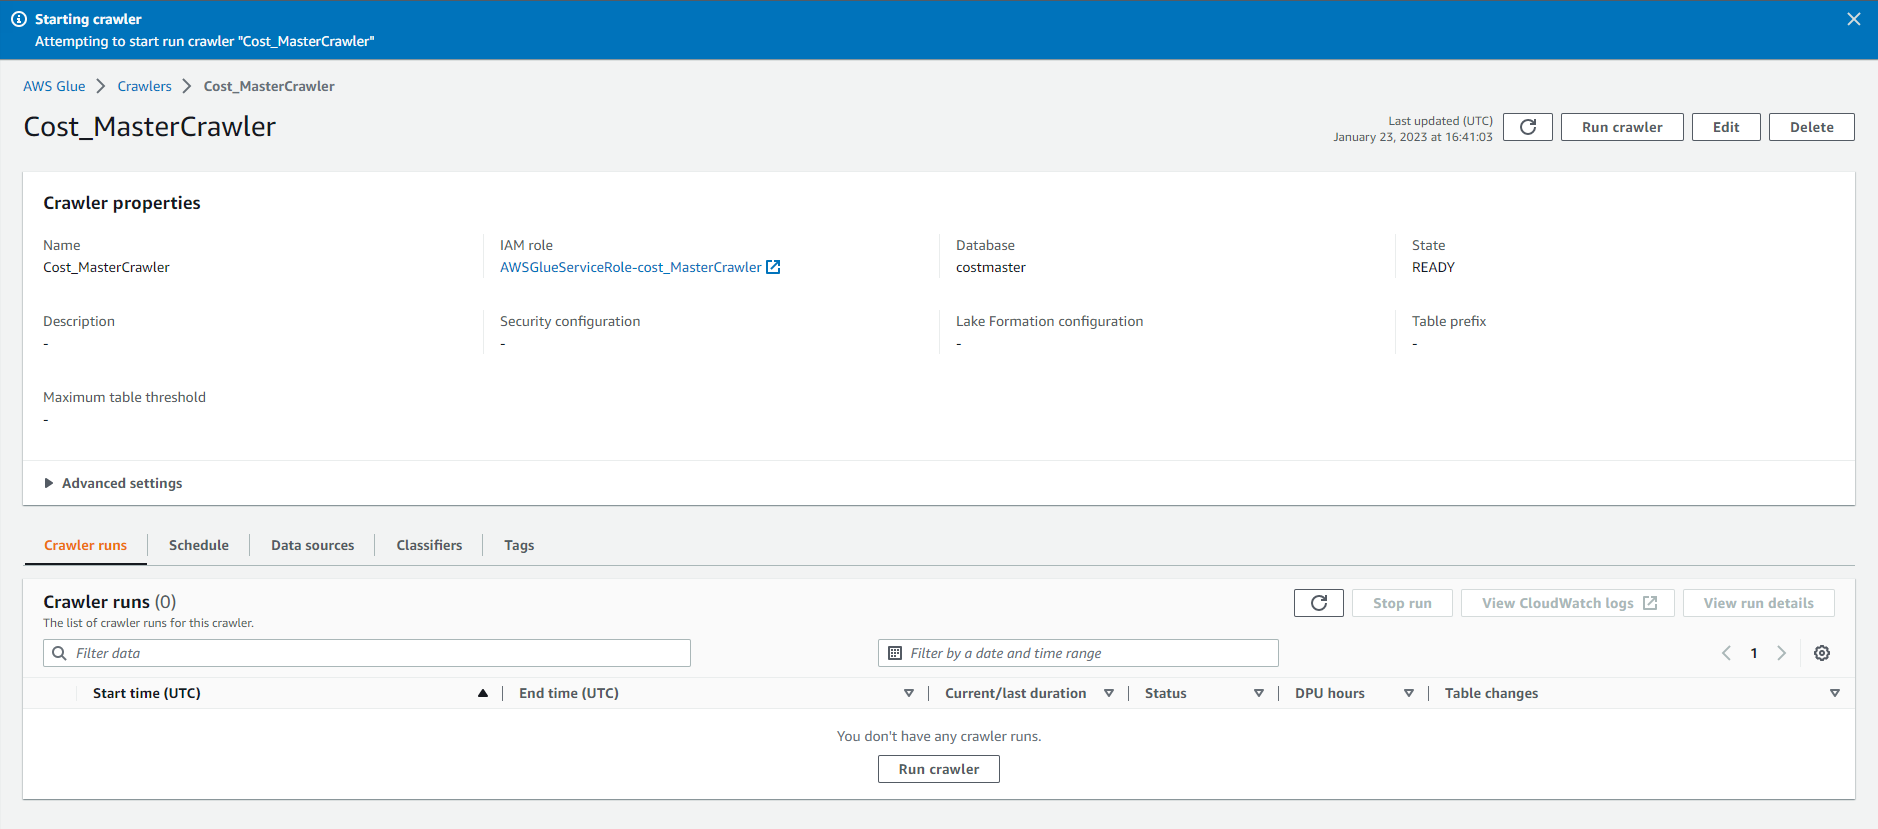
- Initialize run crawler
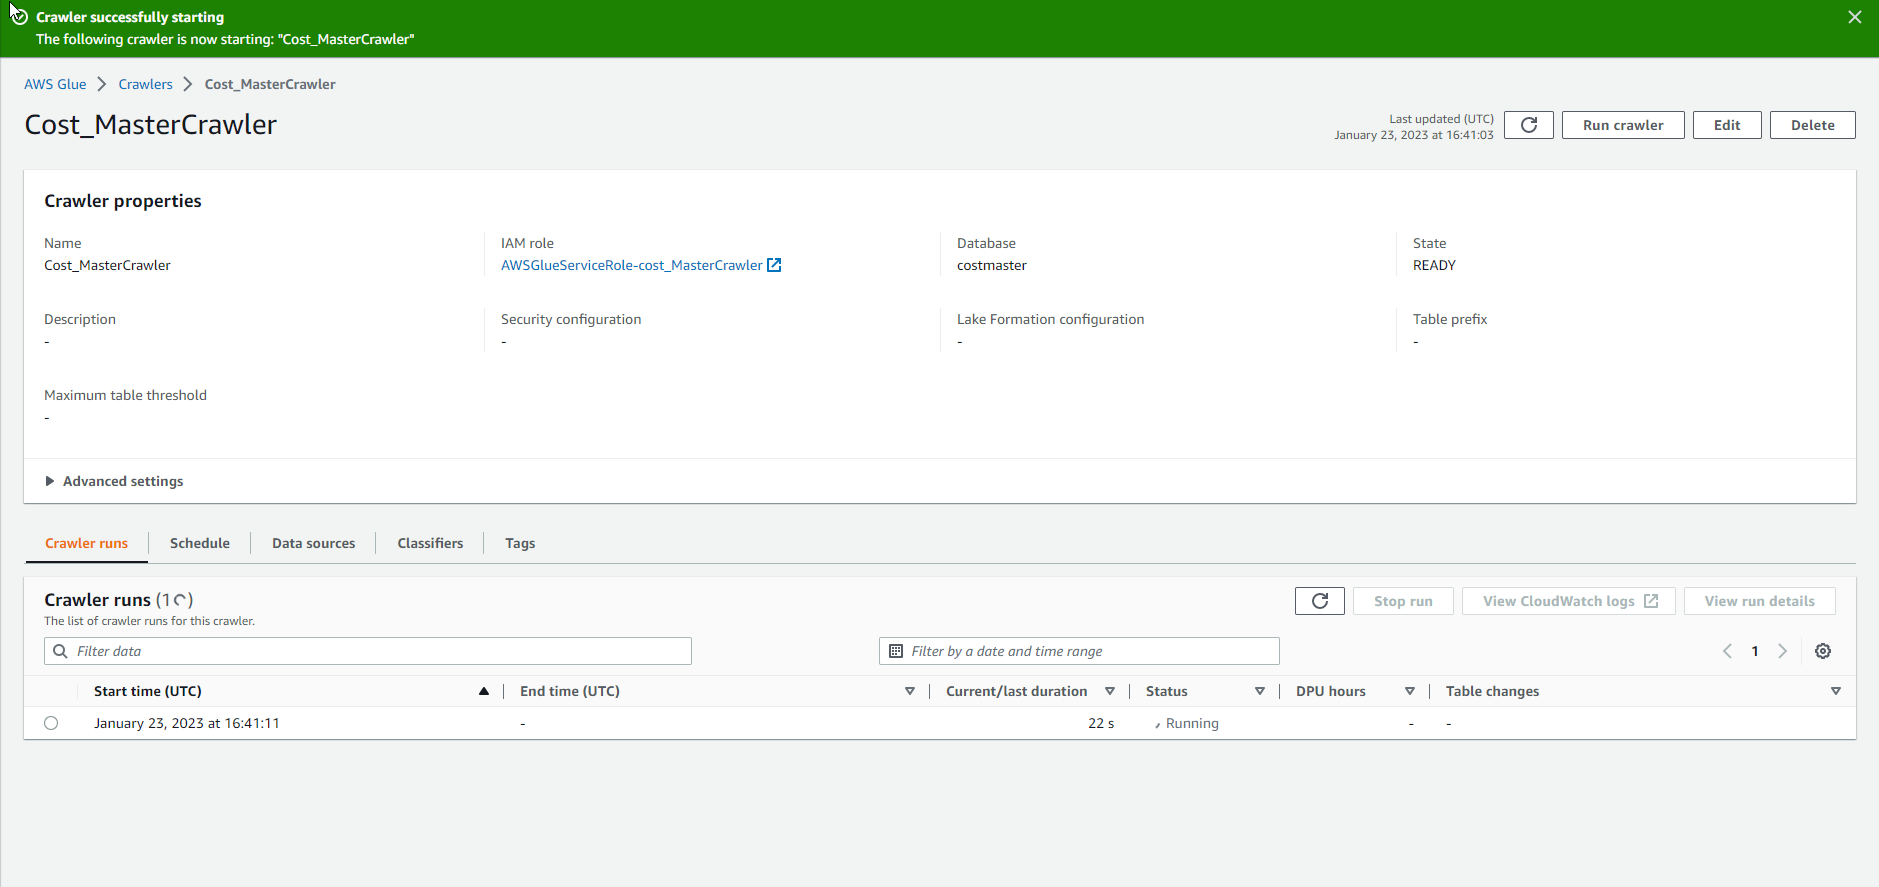
- Run crawler successfully.
- Check the Table of AWS Glue. We see the data table monthly_report
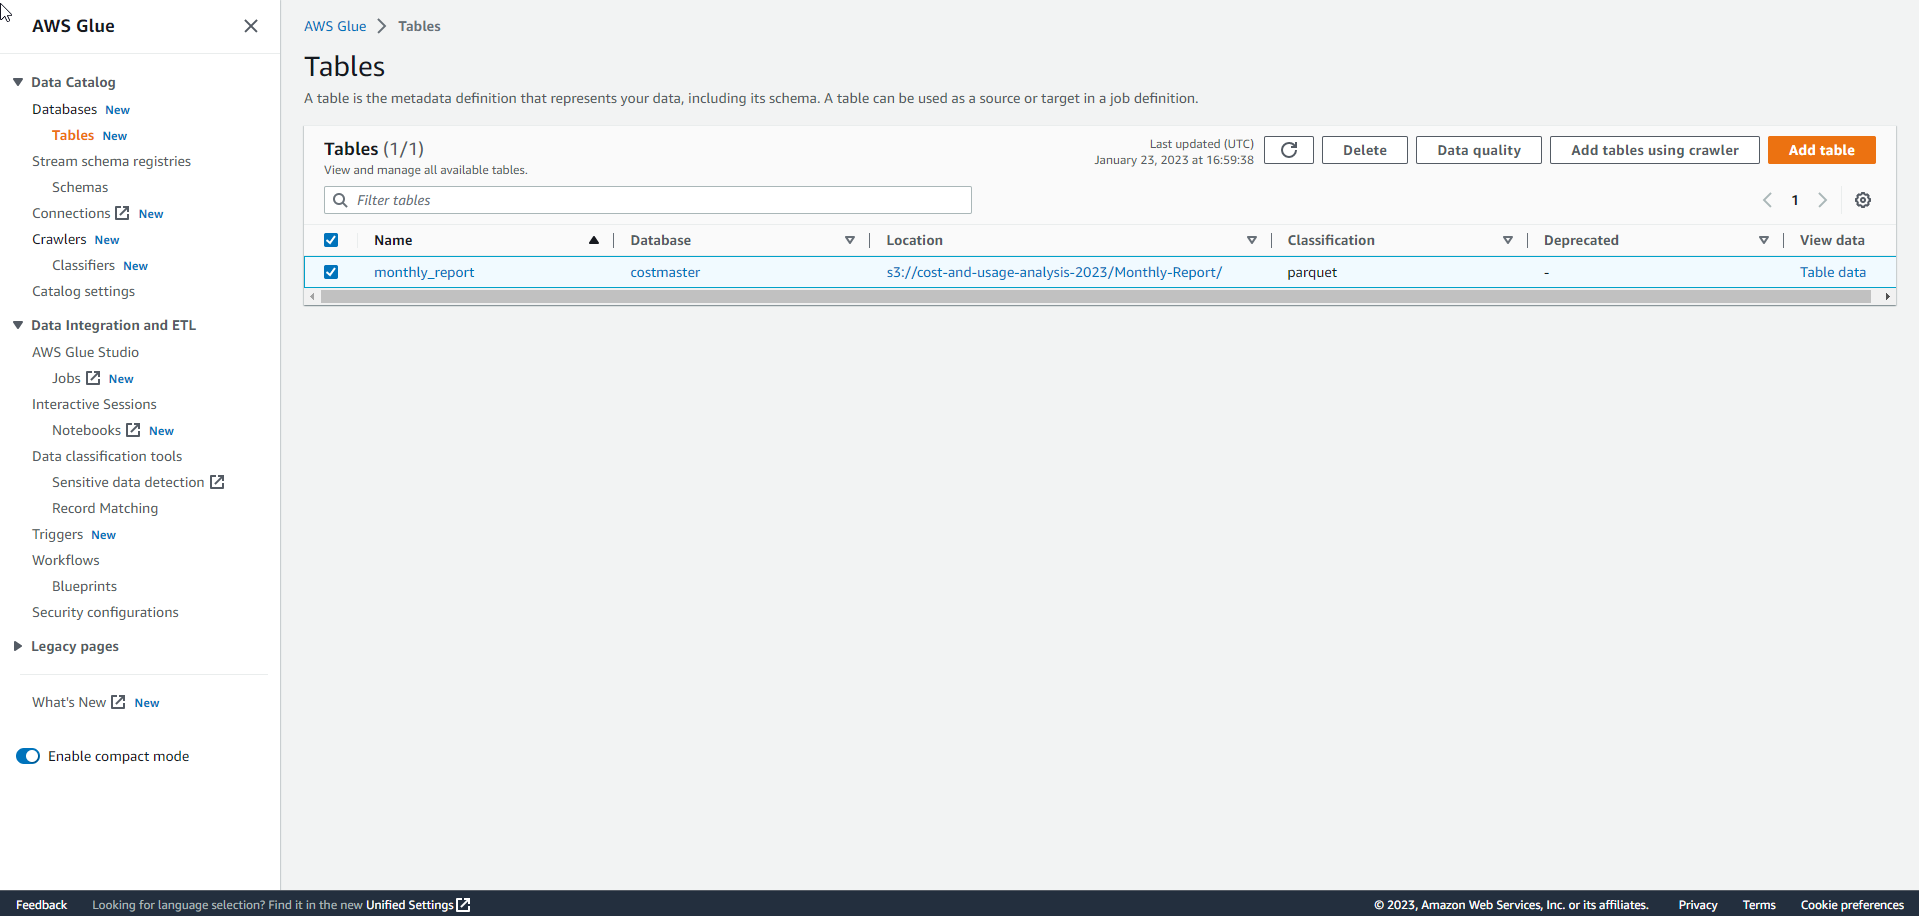
- View detailed information of the data table.